How Statistical Models Identify Value Discrepancies Across UK Betting Markets for Layered Multi-Sport Wagers Involving Soccer, Turf Racing, and Court Events
Written by Petra Becker · Aug 28, 2026
How Statistical Models Identify Value Discrepancies Across UK Betting Markets for Layered Multi-Sport Wagers Involving Soccer, Turf Racing, and Court Events
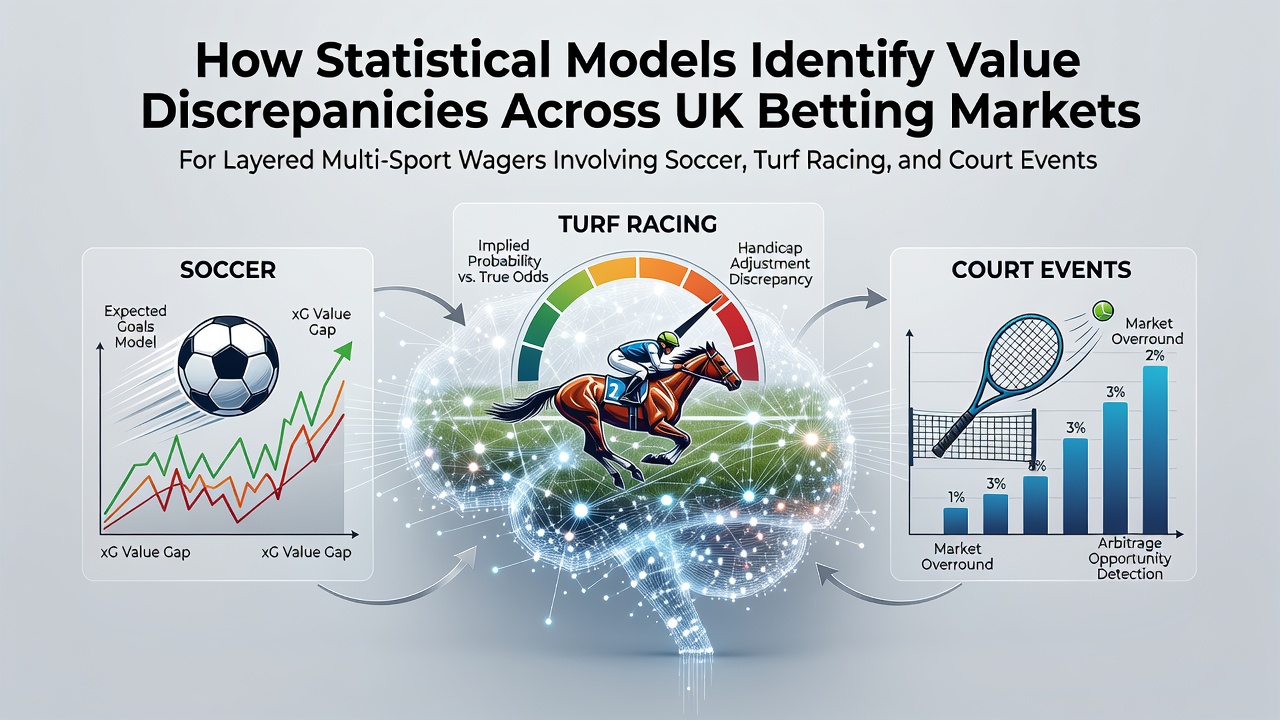
Statistical models detect value discrepancies when calculated probabilities diverge from those implied by bookmaker odds, and this process applies directly to layered multi-sport wagers that combine soccer outcomes, turf racing results, and court events such as tennis matches across UK platforms in August 2026.
Core Principles of Value Identification
Models start by converting odds into implied probabilities then compare those figures against independent estimates derived from historical data and performance metrics, while adjustments for market margins follow immediately so that positive expected value emerges only when model probability exceeds the adjusted implied figure, and this comparison repeats across individual events before any layering occurs.
Models Applied to Soccer Markets
Poisson distributions and bivariate extensions estimate goal counts in soccer fixtures using team attack and defense ratings plus situational variables such as home advantage and recent form, after which the resulting scoreline probabilities feed into match outcome calculations that flag discrepancies when model-derived win probabilities sit higher than those embedded in decimal odds offered by UK operators.
Approaches for Turf Racing Events
Regression models and machine learning classifiers assess horse performance on turf surfaces by incorporating pace figures, going conditions, distance suitability, and jockey statistics, after which probability outputs for win and place positions highlight value when the model assigns higher likelihoods than those reflected in current betting prices.
Tennis and Court Event Frameworks
Elo rating systems and point-based simulations evaluate player matchups on different court surfaces by factoring serve percentages, return efficiency, and fatigue indicators from prior rounds, and these estimates generate set and match probabilities that surface discrepancies whenever model figures exceed implied probabilities from live or pre-match odds.
Integration for Layered Multi-Sport Wagers
Researchers combine outputs from the three sport-specific models through copula functions or Monte Carlo simulations that account for correlation between events, since independent multiplication would ignore shared factors such as weather patterns or scheduling overlaps, and the joint probability distribution then gets compared against the product of adjusted bookmaker odds to reveal whether the layered wager carries positive expected value.
Data Inputs and Market Calibration
High-frequency price feeds from multiple UK bookmakers supply the raw odds, while official results databases and performance tracking services provide the training data, and models undergo daily recalibration to incorporate the latest results so that systematic biases in any single market become visible through persistent divergence between model and market probabilities.
Practical Detection Process
Analysts run automated scans that flag candidate events where the gap between model and market exceeds a predefined threshold, then layer qualifying selections only after correlation checks confirm the joint probability still supports value, and this sequence repeats throughout the day as new information arrives from ongoing matches and races.
Evidence from Research Sources
Studies published in the Australian Gambling Research Centre reports demonstrate that multivariate probability models consistently identify edges in combined sport markets when inputs remain current and correlations receive proper treatment, while additional work from North American academic groups shows similar patterns in cross-sport portfolios once liquidity and margin differences receive explicit adjustment.
Conclusion
Statistical models therefore serve as systematic tools that convert raw performance data into probability estimates, compare those estimates against prevailing odds across soccer, turf racing, and court events, and isolate layered combinations where discrepancies produce positive expected value under current UK market conditions.