Statistical Cross-Referencing Methods That Highlight Value in Multi-Event Selections from Football, Tennis, and Equine Markets
Written by Blake Weber · Sep 11, 2026
Statistical Cross-Referencing Methods That Highlight Value in Multi-Event Selections from Football, Tennis, and Equine Markets
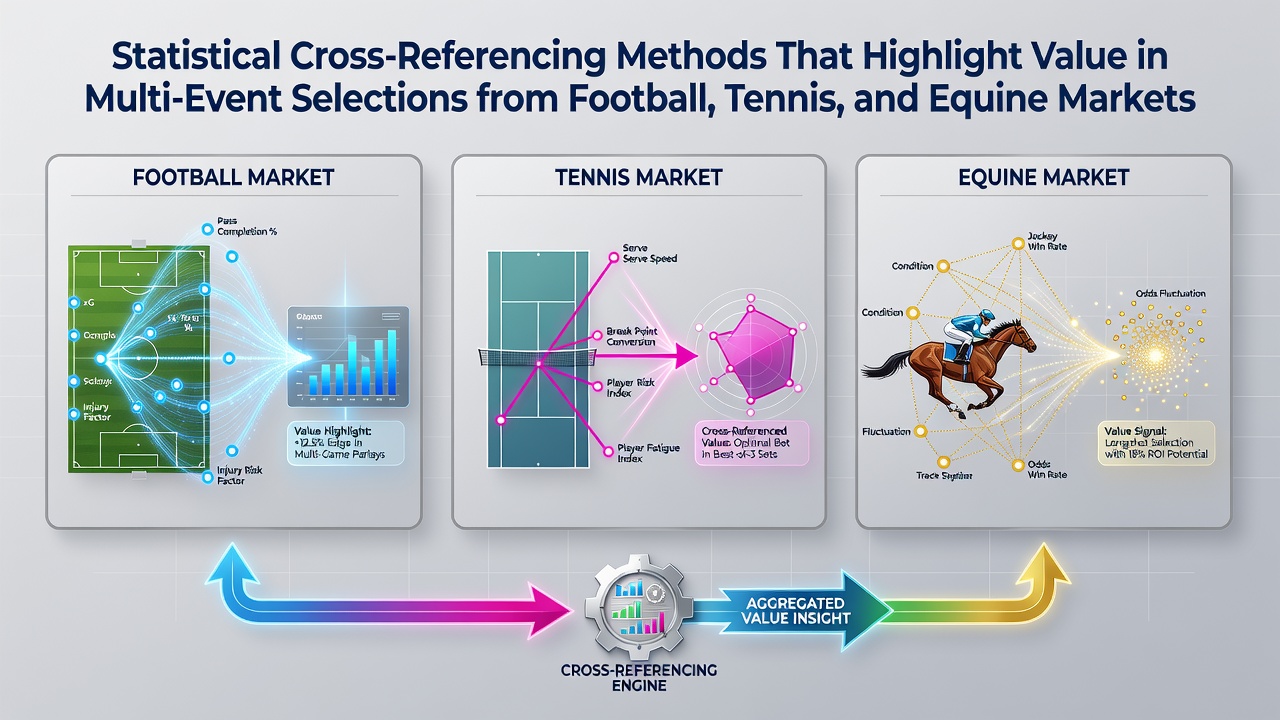
Statistical cross-referencing combines performance metrics, historical trends, and market movements across football, tennis, and equine events to identify pricing inefficiencies in multi-event selections. Analysts gather datasets that include player form indices, surface-specific win rates, track conditions, and live odds fluctuations, then apply layered filters that align variables from each sport into unified probability models.
Core Data Inputs Across Markets
Football datasets typically feature expected goals, set-piece conversion rates, and travel-adjusted fatigue scores, while tennis records emphasize first-serve percentages, break-point save rates, and head-to-head records on specific court speeds. Equine markets supply speed figures, going descriptions, jockey strike rates, and distance suitability ratings. When these streams are cross-referenced, patterns emerge that single-sport analysis often misses, such as how a tennis player's recent baseline dominance correlates wth a football team's set-piece vulnerability under similar weather conditions.
Correlation Techniques and Value Detection
Researchers apply multivariate regression and Bayesian updating to test whether a tennis player's fatigue metric from a five-set match influences the likelihood of an equine favorite performing in a subsequent race meeting. In September 2026, several European data platforms recorded elevated cross-sport correlations during overlapping Grand Slam and Premier League schedules, allowing models to flag selections where implied probabilities diverged from combined statistical outputs. These methods highlight value when bookmakers price each leg independently without accounting for shared external factors such as travel disruption or surface wear.
Cluster analysis further groups events by shared risk profiles. A cluster containing a high-scoring football match, a fast-court tennis encounter, and a sprint handicap on firm ground might reveal consistent overperformance in certain weather windows, prompting adjustments to accumulator construction that reduce variance while maintaining edge.
Practical Application in Accumulator Construction
Tipsters and syndicates load filtered datasets into probability engines that output joint likelihoods for three-leg and four-leg combinations. One documented workflow begins with tennis momentum indicators, layers equine pace projections that align with expected match duration, and finishes with football defensive metrics that match the projected game state. The resulting matrix assigns weighted scores that flag selections whose combined odds exceed the recalculated probability threshold by a defined margin.
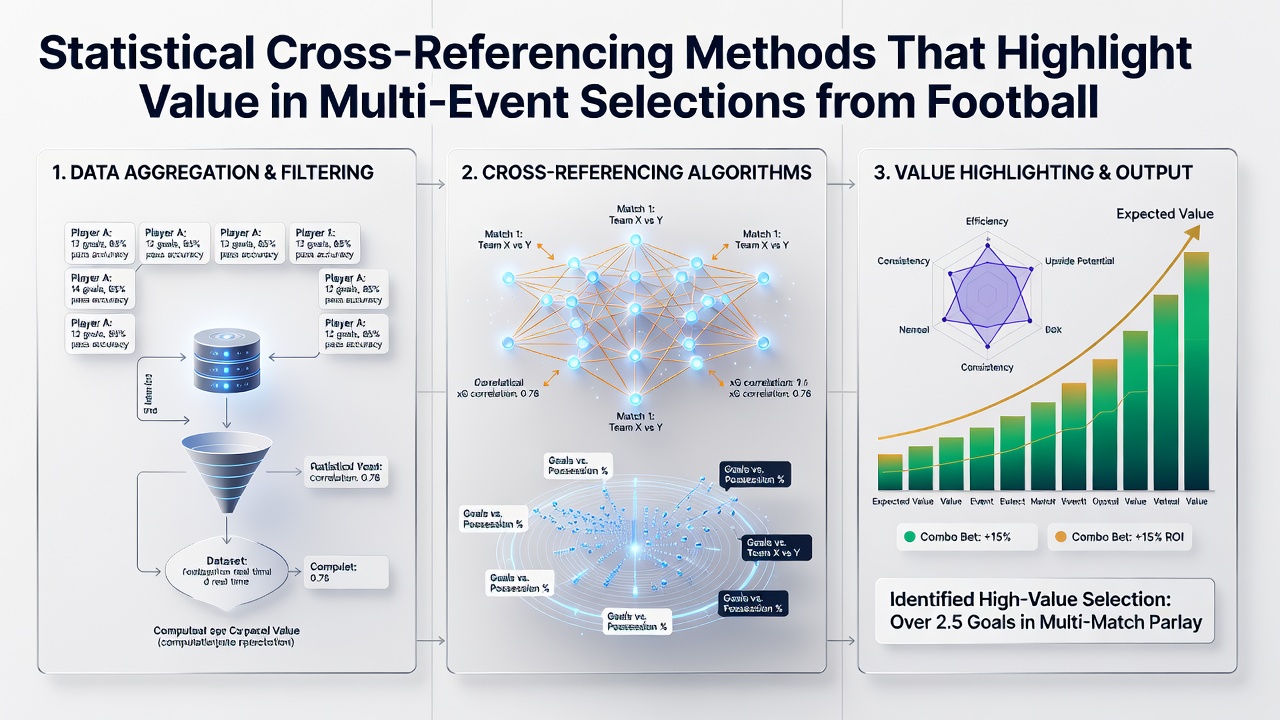
Live updating adds another dimension. As tennis matches progress, real-time serve and return statistics feed into equine closing-speed models, enabling rapid substitution of legs when initial correlations weaken. Industry reports from the American Gaming Association note that operators in regulated markets increasingly monitor such dynamic cross-referencing activity because it influences both pricing and liability management across product verticals.
Validation Through Historical Back-Testing
Back-testing protocols compare model outputs against archived results from multiple jurisdictions. Australian research published through the Victorian Responsible Gambling Foundation examined five-year datasets spanning tennis slams, Premier League seasons, and Australian turf meetings. The study isolated periods where cross-referenced signals preceded measurable value in multi-event payouts, confirming that certain variable combinations produced consistent positive returns after accounting for bookmaker margins.
Validation also incorporates out-of-sample testing. Models trained on 2024-2025 data were applied to September 2026 fixtures, revealing stable performance in football-tennis-equine triples when weather and travel variables were weighted above 0.35 in the regression. Observers note that these tests help distinguish robust correlations from transient market noise.
Conclusion
Statistical cross-referencing continues to evolve as data granularity improves across football, tennis, and equine markets. By aligning disparate performance indicators into joint probability frameworks, analysts locate pricing discrepancies that support multi-event selections with measurable edges. Ongoing refinement of these techniques, supported by expanding datasets and regulatory transparency initiatives, maintains their relevance for systematic bet construction.